September 10, 2026
BCRA Mini-RAG
A cited-clause RAG over Argentine FX regulation: ask what a BCRA circular says and get a Comunicación “A” citation, or silencio.
Stack: Python 3.11+, FastAPI, Gradio, Chroma, pydantic v2, OpenSpec, uv
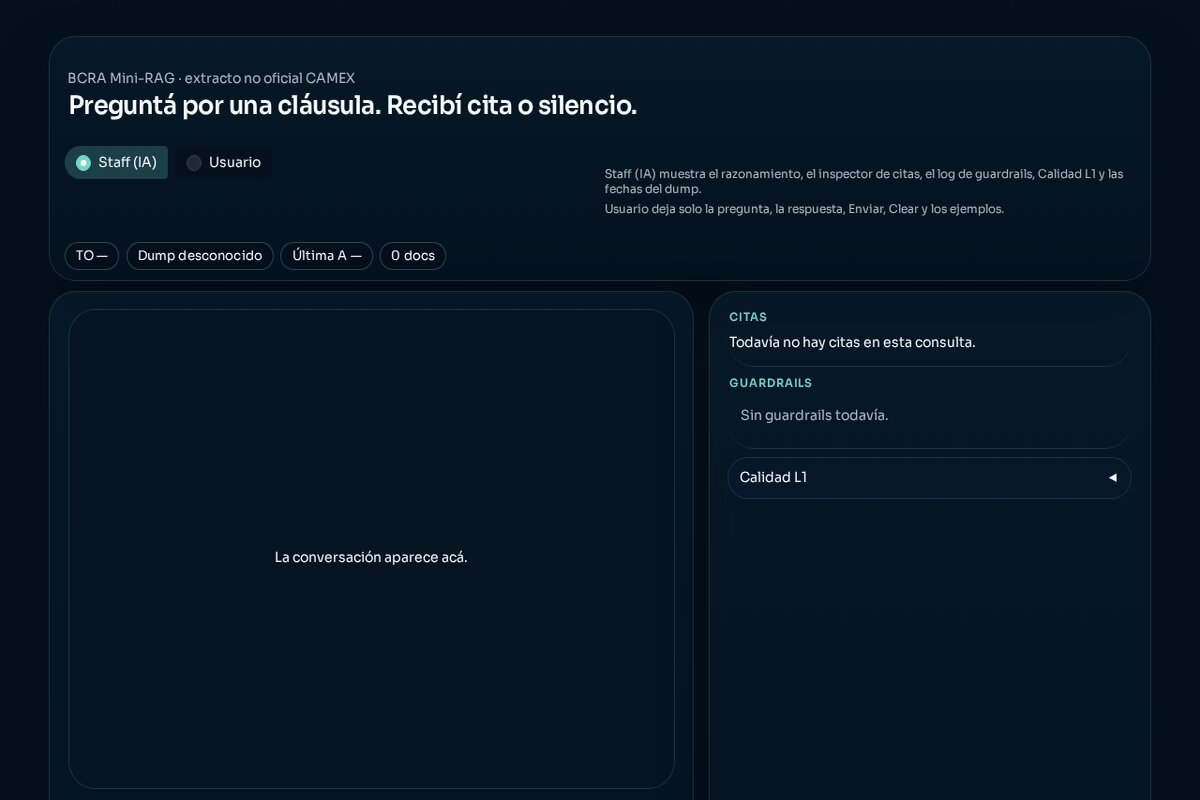
BCRA Mini-RAG is a small RAG assistant over Argentine foreign-exchange regulation (BCRA CAMEX). Ask what a circular says and it cites the Comunicación “A” number and the punto (clause number), or it answers silencio. It is not a general BCRA chatbot, and it is not legal advice.
CAMEX is a living corpus: decades of Comunicaciones “A” plus a texto ordenado (consolidated text) that states the rule in force hoy (today). I wanted an assistant that answers a clause question from that corpus and then stops. It cites the communication and the punto, or it refuses. It does not chat around the regulation.
The service ingests the official tipo-A catalog (Com. A 13, 1981 to the present) and the current Exterior y Cambios texto ordenado (TO). It refreshes when new Comunicaciones A appear or the TO checksum changes, and it retrieves from a Chroma index. Generation is structured: answer, deontic finding, and citations. A query that names Com. A NNNN routes to that document. “Vigente” or “hoy” (in force, today) prefers the TO plus later Comunicaciones A. Guardrails log every turn. If the model cannot ground a clause, the finding is silencio and the UI abstains.
The code was written spec-first. Ingest, retrieval, query answering, guardrails, the observatory UI, and L1 evals each started as an OpenSpec change (proposal, requirements, design, and tasks) before the implementation. It is the same loop I used on check-unprotected-keys. The ports, the structured generation contract, and the silencio rule were settled on paper, where they were cheap to change, and the code followed.
The observatory has two layouts. Staff (AI) shows the reasoning, a citation inspector, the guardrail log, L1 quality, and dump dates. User keeps the question, answer, send, clear, and examples. L1 is an operator harness over a 30-question gold set, and its headline metric is an exact citation-id match. The UI only reads the last static results file, and the chat never scores itself. Answers are unofficial excerpts of public bcra.gob.ar documents, current as of the last dump refresh.
To keep inference off paid APIs, embeddings and the LLM run locally: a couple of Qwen models on a GPU with llama.cpp. Quality is not on par with mainstream hosted models.